The Scraper Didn't Fail. The Payload Changed.
The job did not crash. That would have been easier.
on this page
The job did not crash. That would have been easier.
For a while, the grocery scraper pulled Delhaize data, stored it, and looked healthy. Then the payload changed shape just enough to stay valid and just enough to stop being useful. A field renamed itself. Another moved. The HTTP response still came back 200. The parser still ran. The downstream data still filled the database. Only later did the bad rows show up: wrong prices, missing products, empty summaries, and no obvious place to blame.
That is the worst kind of integration failure. Everything looks successful until you ask a human to trust the output.
The first diff I care about looked like this:
{
  "status": "completed",
  "products_found": 142,
  "summary": "..."
}
Then, without warning:
{
  "status": "success",
  "products_scanned": 142,
  "result_summary": "..."
}
Nothing about that second payload is obviously broken. It is still JSON. It still contains the count. It still describes the run. But if your code expects status == completed and products_found, the run suddenly becomes half invisible. You do not get a loud exception. You get a silent lie.
The Part That Broke
Undocumented integrations do not usually fail like official APIs do. They drift.
In this case, the scraper was reading a grocery site that did not owe us stability. The site was free to rename keys, split objects, or move a field into a nested structure whenever the frontend changed. The scraper could not control that. All it could do was notice when the shape changed and refuse to pretend the output was still trustworthy.
That is the first lesson: when the source is undocumented, a “successful fetch” is not the same thing as a “usable fetch.”
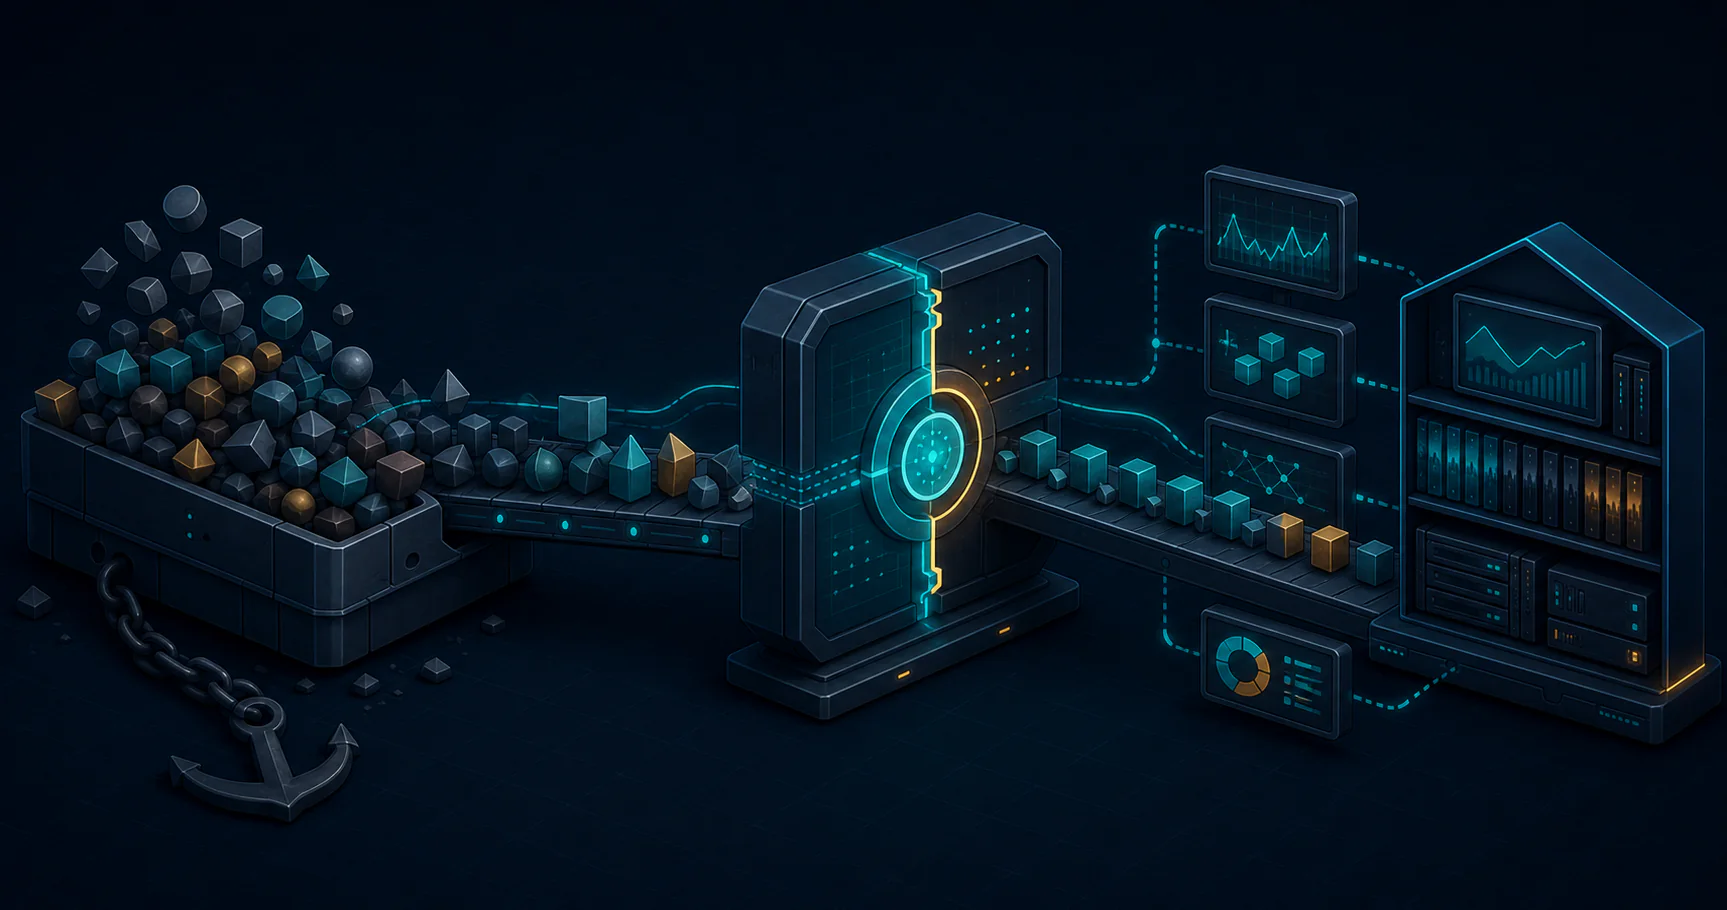
The payload drift did not just change one field. It changed the meaning of the whole run. A job that used to tell us “these are the products, this is the status, here is the summary” became a job that looked fine at the transport layer but no longer matched the contract our code had built around it.
If you let raw upstream fields leak into business logic, the failure spreads. The database accepts the row. The UI renders the row. A report uses the row. Everyone is now depending on a field that used to mean one thing and now means another.
The Adapter Layer
The fix is not to be cleverer in the parser. It is to stop letting the parser be the rest of the system.
I want one small seam where raw payloads enter, get normalized, and become a stable internal shape. Everything else reads the stable shape only.
In practice, that means the adapter knows about ugly upstream reality and the rest of the code does not:
def normalize_run(payload: dict) -> dict:
    status = payload.get("status", "").lower().strip()
    if status in {"success", "completed"}:
        status = "success"
    elif status in {"failed", "error"}:
        status = "failed"

    products = payload.get("products_found")
    if products is None:
        products = payload.get("products_scanned")

    summary = payload.get("summary")
    if not summary:
        summary = payload.get("result_summary", "")

    return {
        "status": status or "unknown",
        "products": products,
        "summary": summary,
        "raw": payload,
    }
That function is not magic. It is just a place where drift can be absorbed without forcing every consumer to relearn the upstream schema.
More importantly, it makes the hidden assumption visible. If products_found disappears, the adapter is where we see it. If result_summary starts coming through empty, the adapter is where we log it. If the site adds a new field we do not know yet, the adapter is where we decide whether to ignore it or teach the system about it.
The point is not to make the scraper perfect. The point is to make one part of it honest.
Why Silence Is Dangerous
The scary version of schema drift is not the version that explodes. It is the version that lets bad data look normal.
I have seen this in small automation stacks enough times to trust the pattern. An upstream field changes. The scraper keeps returning rows. A dashboard keeps showing counts. A nightly job keeps passing. No alert fires because the code still thinks it is receiving a valid object. By the time somebody notices, the wrong data has already moved through three or four layers.
That is why monitoring belongs next to the adapter, not far away from it.
The adapter should not just normalize. It should also emit signals:
def normalize_run(payload: dict) -> dict:
    known_keys = {"status", "products_found", "products_scanned", "summary", "result_summary"}
    unknown_keys = sorted(set(payload) - known_keys)
    if unknown_keys:
        log.warning("unknown upstream keys: %s", ", ".join(unknown_keys))

    # normalize fields here...
That warning matters because the first sign of drift is often not a broken field. It is a new field. A renamed key. An extra nesting level. A value that changed from string to object. If you are not logging the shape of what you receive, you are waiting for users to discover the breakage for you.
The other useful check is a snapshot diff. Save one payload per run. Compare it to the previous one. If the shape changes, flag it. Not every change is bad, but every change deserves a human glance.
You do not need a giant observability stack for this. You need a cheap alarm for “the source is no longer speaking the same language.”
The Design Rule
The rule I would keep from this whole mess is simple:
Do not let undocumented payloads touch business logic directly.
That means no random payload["summary"] lookups in UI code. No silent fallback chains spread across four services. No “it worked yesterday” assumptions embedded in a report generator. The upstream schema belongs in one place, and that place should be easy to test.
If I were building this again, I would keep three layers:
- Fetch the raw page or API response.
- Normalize it into a canonical internal model.
- Let the rest of the system consume only the canonical model.
That gives you a clear place to answer the only questions that matter:
- Did the upstream schema change?
- Did we notice?
- Did the adapter preserve the fields we actually care about?
For this Delhaize scraper, that means the run is only “successful” when the normalized fields still match reality. A green HTTP response is not enough. A parsed JSON object is not enough. A clean database write is not enough. If the shape changed and we did not notice, the system did not work. It just failed politely.
What Good Looks Like
The best version of this pipeline is boring.
The fetch step can be messy. The source can be inconsistent. The HTML can be awkward. But once the adapter does its job, the rest of the system should stop caring about those details. It should see stable keys, stable types, and a clear warning when something drifts.
That is what makes the whole thing maintainable. Not perfect parsing. Not clever retry logic. Just a small seam where the scraper admits what it got, tells you what changed, and refuses to smuggle uncertainty into the rest of the stack.
When schema drift is isolated and monitored, the system can absorb a messy upstream site without quietly becoming wrong. That is the real upgrade. Not fewer failures. Better failures. Failures you can see before they spread.
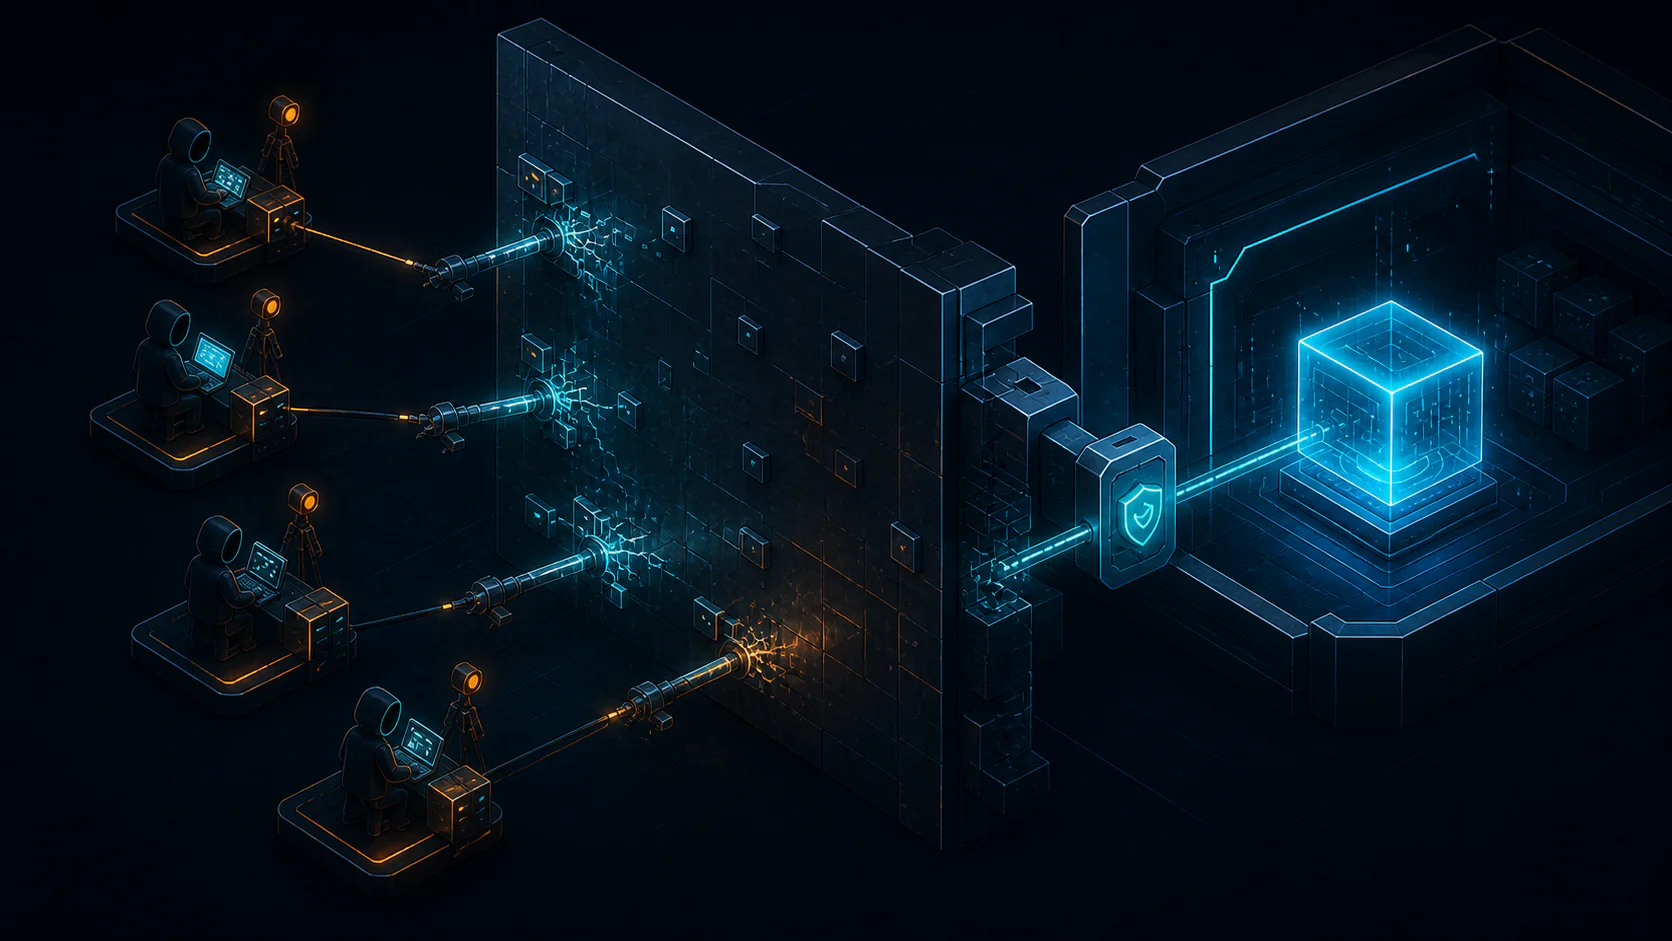 Nothing crashed when the schema shifted; the job just started returning partial records and empty fields. The cost showe
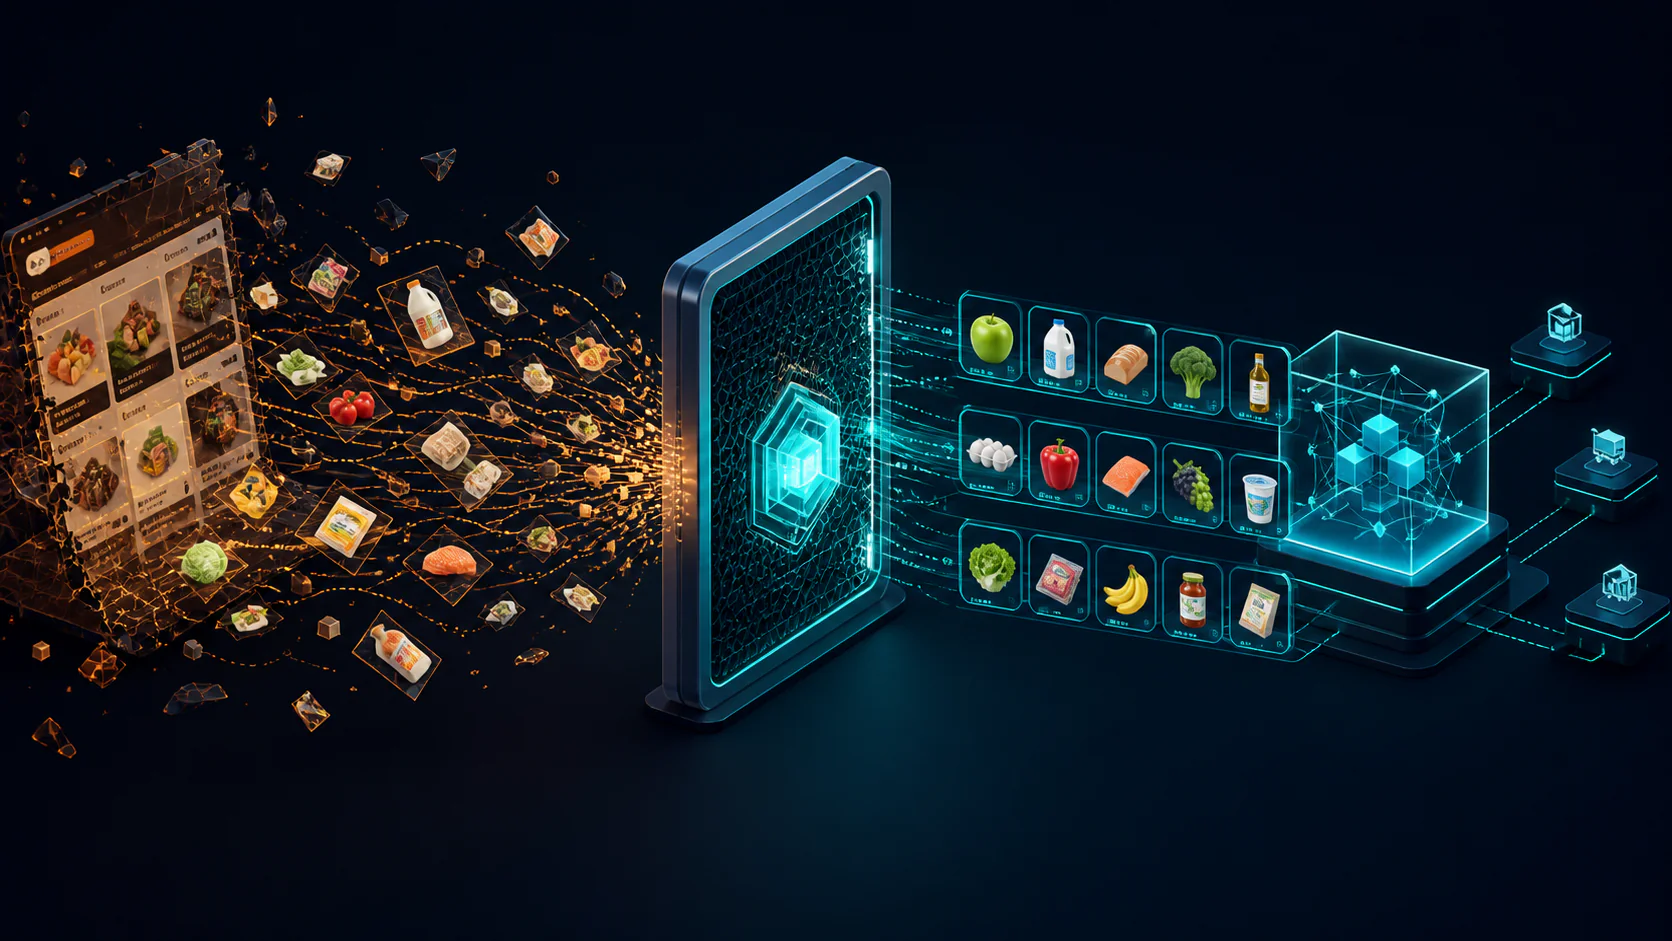 Nothing crashed when the schema shifted; the job just started returning partial records and empty fields. The cost showe
Code Share
This article includes a companion code share with:
- core implementation logic
Available in the repository:
code-share/delhaize-groceries-part-1