SQLite Wasn't the Failure. Silent Job Loss Was.
The most dangerous database bug is not the one that crashes loudly.
on this page
The most dangerous database bug is not the one that crashes loudly.
It is the one that leaves a job looking successful after the write never really landed. A task runs, the UI stays calm, the process keeps going, and somewhere in the middle of that success path a write hits contention, retries are missing or too short, and the work quietly vanishes. No dramatic stack trace. No obvious outage. Just a gap between what the app thought happened and what the database actually accepted.
That is the real reason this stack eventually stopped feeling safe on SQLite.
SQLite is not evil, and it is not fragile in the generic sense people like to imply when they lose a weekend to a migration. It is a very good embedded database. The problem appears when an application uses it in a way that assumes write contention will be rare, short, or easy to recover from. Once the system starts doing real work in parallel, that assumption becomes a liability. The failure mode is not “SQLite corrupts everything.” It is “the application loses work in a way that is hard to notice until later.”
This article is about that difference.
The Failure Mode
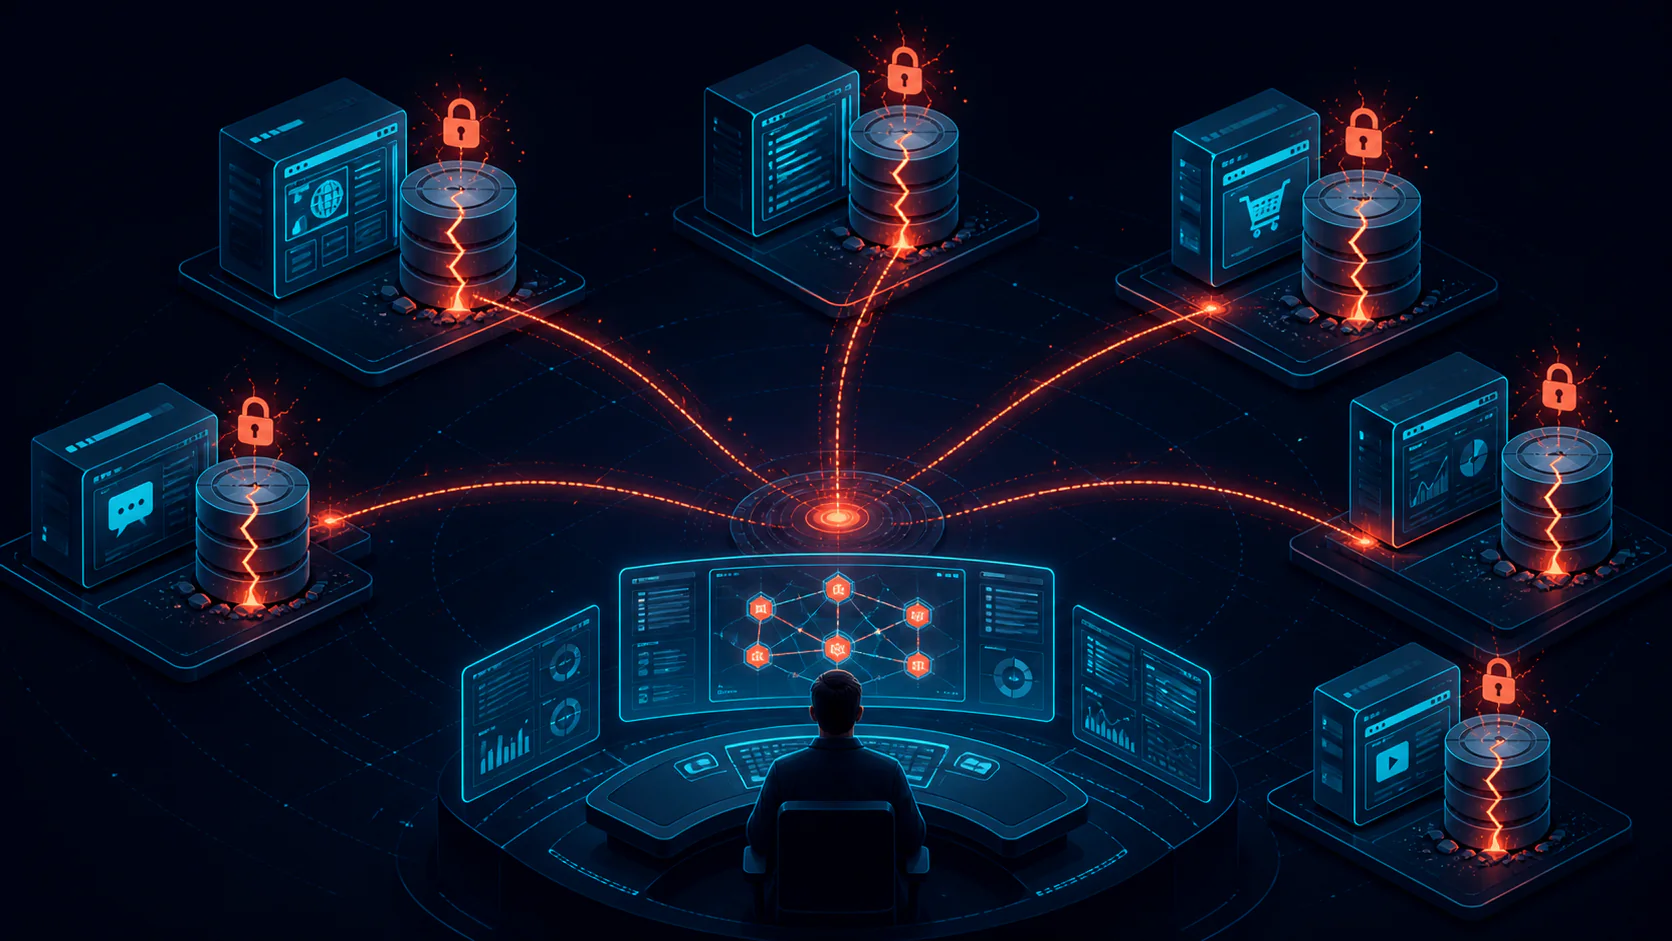
The stack here is not a toy app with one write path and a neat retry loop. It has background jobs, metadata updates, queue state, and multiple pieces of code trying to write at once. In that kind of system, SQLite’s single-writer behavior is not just a theoretical constraint. It becomes a scheduling fact.
When a write collides with another write, the app has to decide what to do. Wait? Retry? Surface the error? Mark the job failed? Keep going?
The dangerous answer is “keep going and hope the caller notices.”
That is how a task can appear complete while its durable state is missing or half-written. A job runner may successfully finish the outer workflow, but one internal persistence step fails on lock contention and the error gets handled too loosely. If the next stage only checks “did the job return?” instead of “did the state transition persist?”, the failure is effectively invisible.
This is why the issue felt like a silent loss problem, not a database problem.
SQLite was doing what SQLite does: enforcing a single-writer model and rejecting writes when the database is busy. The application behavior around that constraint was the weak link. A system can be technically correct and still operationally dangerous if it treats write failures as a temporary annoyance instead of a durable state transition.
Why It Took So Long To Notice
The reason these bugs sting is that they are plausible.
In a lightly loaded system, SQLite works beautifully. It is fast, easy to inspect, and simple to move around. You can build quite a lot on top of it before the edge cases show up. That creates a false sense of confidence: if the stack has been fine for months, surely the next failure is just a one-off lock timeout.
But contention bugs scale nonlinearly.
At first you get a few retries. Then a few missed updates. Then a queue item that was “handled” but never fully persisted. Then the job that gets marked done in memory but never gets a durable final state. By the time anyone notices, the app has already taught itself a bad habit: treat a failed write as something to work around instead of something to stop on.
That is the silent part of the failure.
There is no single dramatic event where SQLite becomes unusable. There is just a gradual increase in the number of places where “busy” means “maybe later” and “maybe later” eventually means “never actually recorded.” If the application does not insist on stronger guarantees, the database can be perfectly healthy while the job pipeline is not.
What The Evidence Looked Like
The useful evidence was not “SQLite is slow.” It was “writes were getting lost or deferred in ways the system did not make visible enough.”
That distinction matters, because it changes the fix.
If the issue were raw performance, the answer would be profiling, indexing, or moving hot tables around. If the issue were corruption, the answer would be backups and repair. But the actual symptom set pointed to concurrency and state handling. The app was depending on a write model that did not match the amount of work it was trying to do.
In practice, the failure showed up as:
- jobs that moved forward even when one of the write steps did not persist cleanly
- state that was fine in memory or in the immediate process flow, but missing when reread later
- retries that helped sometimes, but not enough to make the workflow trustworthy
- no clear signal at the outer level that a write conflict had happened at all
That last point is the one that matters most. If the system cannot tell the operator “this job had contention and did not fully commit,” then the problem is not just reliability. It is observability.
Once we framed the issue that way, the shape of the solution became much clearer. The goal was not to defend SQLite as a general-purpose concurrency engine. The goal was to reduce the number of times the stack could enter this bad state in the first place.
Why PostgreSQL Helped
Moving to PostgreSQL did not make the whole system magically correct. It did, however, reduce the specific kind of failure that was hurting us.
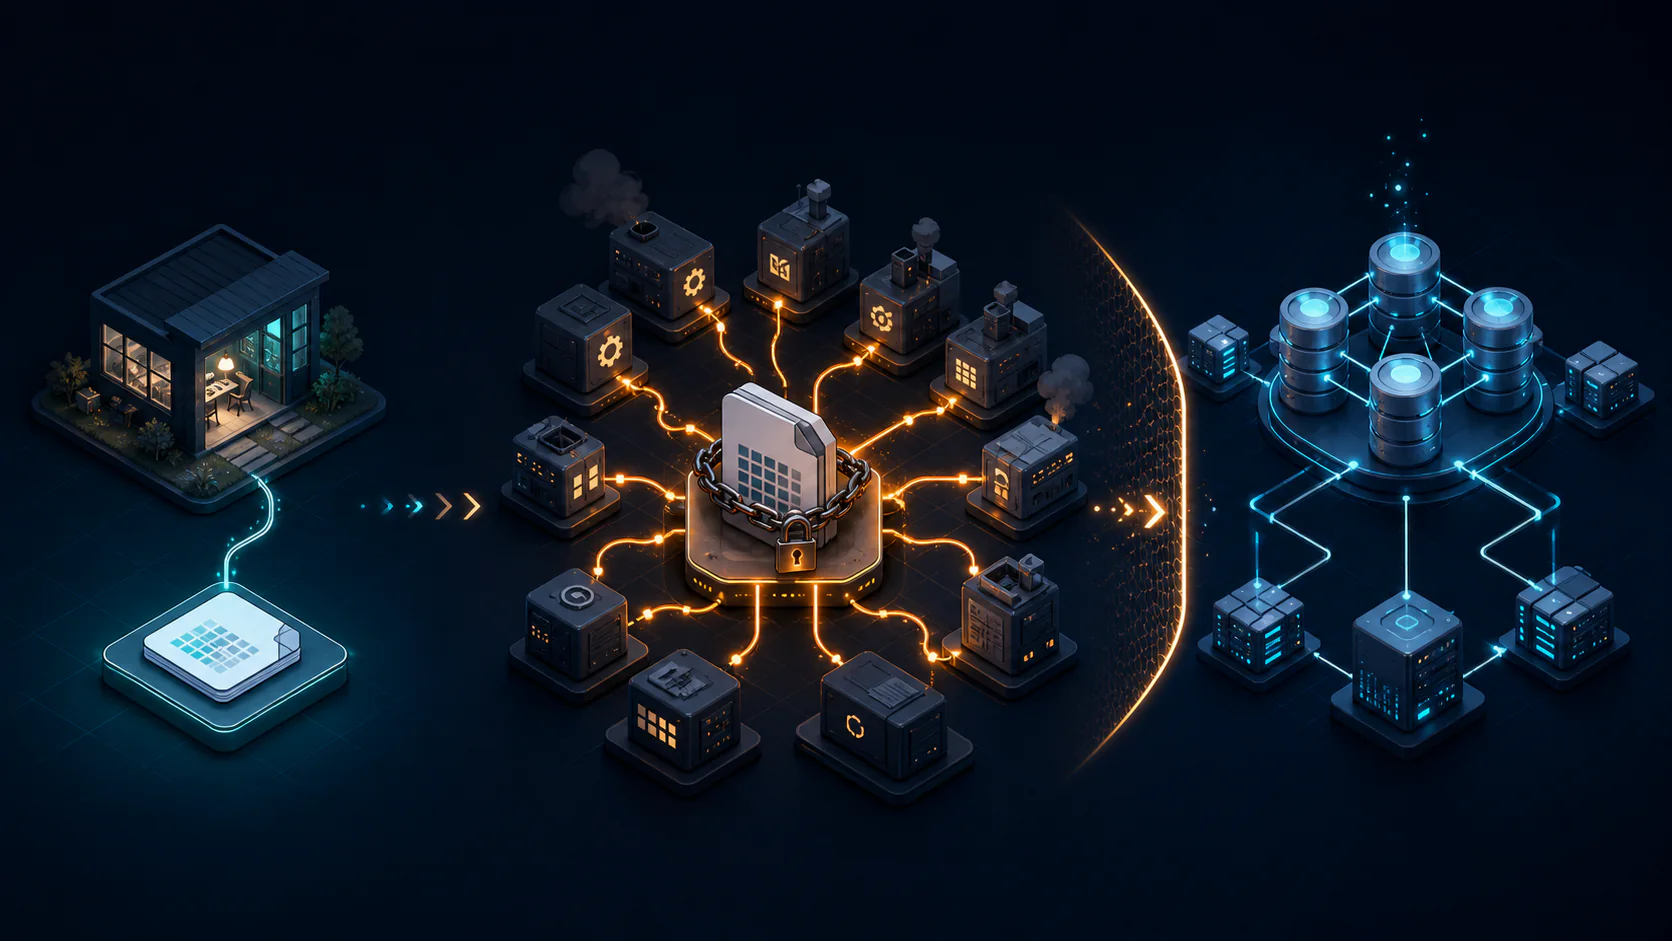
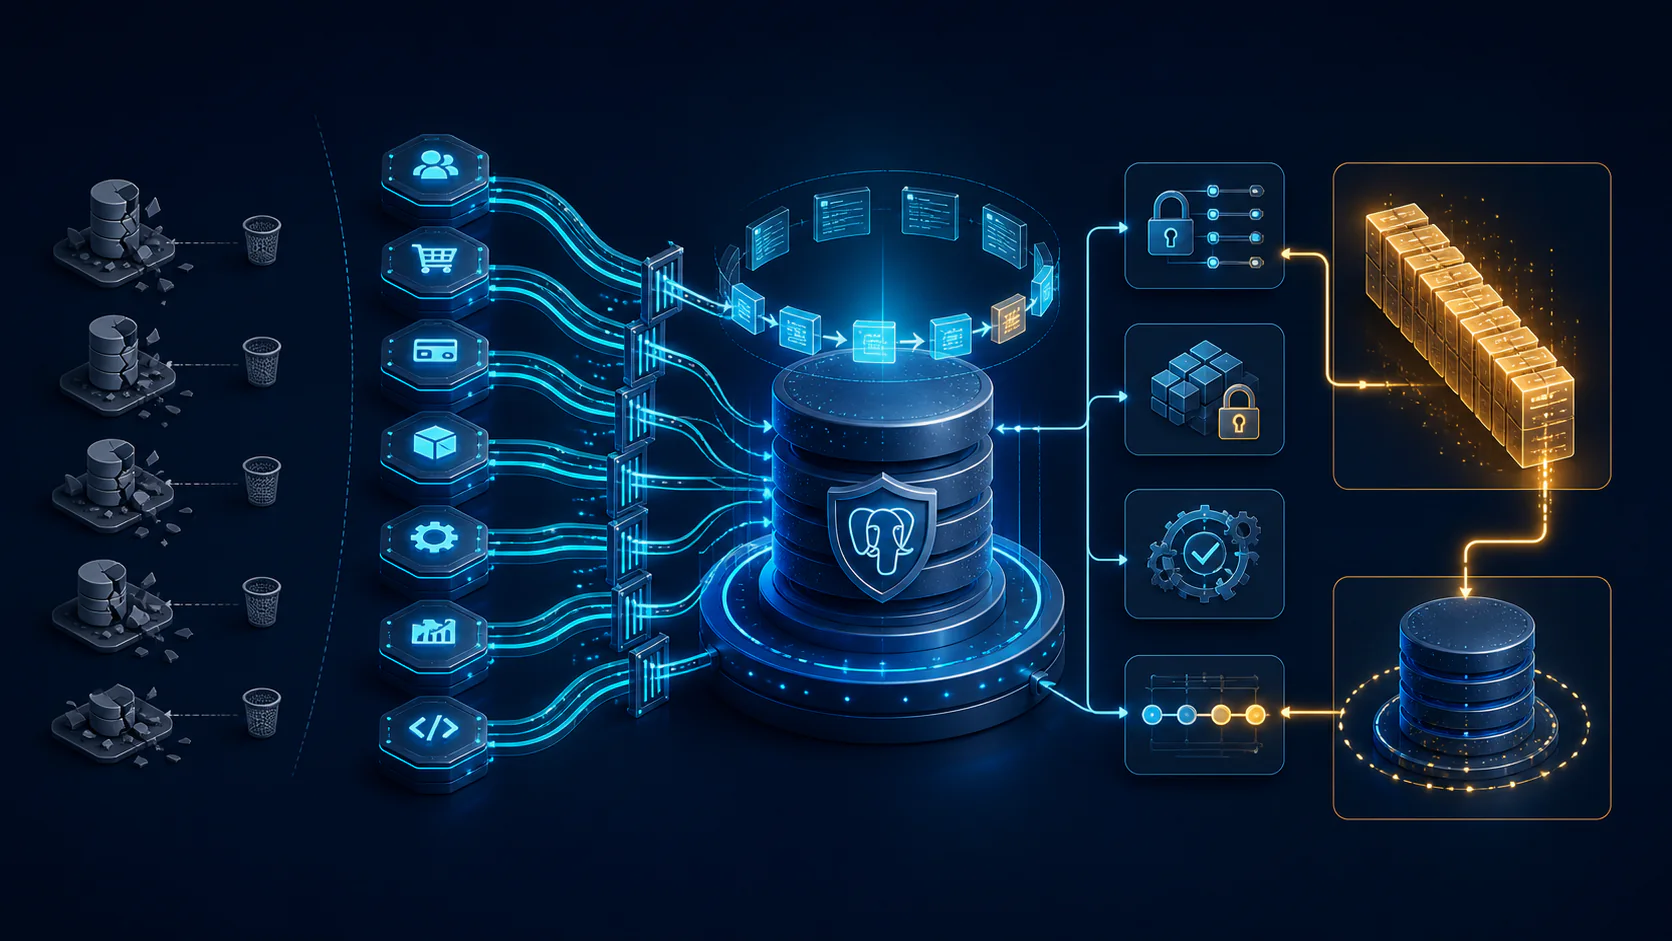
The core benefit is that PostgreSQL is designed for a more concurrent workload. It handles multiple writers more gracefully, gives you better tools for transaction boundaries, and makes it harder for app code to accidentally pretend a write succeeded when it did not. You still have to write good code, but the database stops being the first thing that pushes back against ordinary parallel work.
That changes the operational shape of the stack in a few important ways:
- writes are less likely to collide at the level the app was experiencing them
- state transitions become easier to reason about because the database model fits the workload better
- retry logic becomes a backup plan instead of the main line of defense
- the chance of a job quietly disappearing between “ran” and “persisted” goes down
The important word there is “chance.” PostgreSQL does not eliminate bugs. It just makes the concurrency surface much less hostile for this workload.
That is why the migration made sense even though SQLite itself was not broken. The job was not to prove one database superior in the abstract. The job was to make silent job loss less likely in this stack.
The Migration Tradeoff
Moving from SQLite to PostgreSQL always comes with a cost, and it is worth stating plainly.
SQLite is easy to bundle, easy to inspect, and easy to reset. It is a single file you can back up, copy, and reason about without a separate server process. For small systems, or systems with mostly read traffic and simple writes, that is a very attractive trade.
PostgreSQL asks for more. You manage a server. You manage credentials. You deal with networking, backups, and migration planning. You accept one more moving piece in exchange for better concurrency behavior and stronger guardrails around write-heavy workflows.
That is not a free lunch.
But the right comparison is not “SQLite is simpler.” The right comparison is “what kind of failure is more expensive for this stack?” If the worst case is a more complicated database service, PostgreSQL may be overkill. If the worst case is a background job that silently loses state after a write conflict, the extra operational cost is easy to justify.
The migration also changes how you think about the app. Once the database can support more realistic concurrent behavior, the application no longer gets to hide behind casual write logic. You can still write bad retry code, but now it is easier to see the shape of the bad code because the database is not the bottleneck pretending to be the whole problem.
What Actually Changed
The takeaway is not “SQLite bad, PostgreSQL good.”
The takeaway is that a database choice is really a workload fit question. SQLite was fine until the stack reached the point where write contention started creating invisible failure modes. After that, the issue was no longer whether SQLite could store the data. The issue was whether the application could keep pretending a busy write was a harmless edge case.
It could not.
That is why the move to PostgreSQL mattered. Not because it made every bug disappear, and not because it turned the app into a perfectly disciplined system, but because it reduced the number of opportunities for silent loss. The stack became easier to trust because the storage layer matched the concurrency shape of the work.
If you are running something similar, the question is not “can SQLite handle one more job?”
The better question is:
Can your app prove that the thing it said it wrote actually exists after contention, retries, and the next process restart?
If the answer is no, the problem is already larger than SQLite.
 The Error Nobody Reads Twice
 Why SQLite Was Right, and Why It Stops Being Right
 Six Services, One Pattern of Failure
 What PostgreSQL Actually Fixes